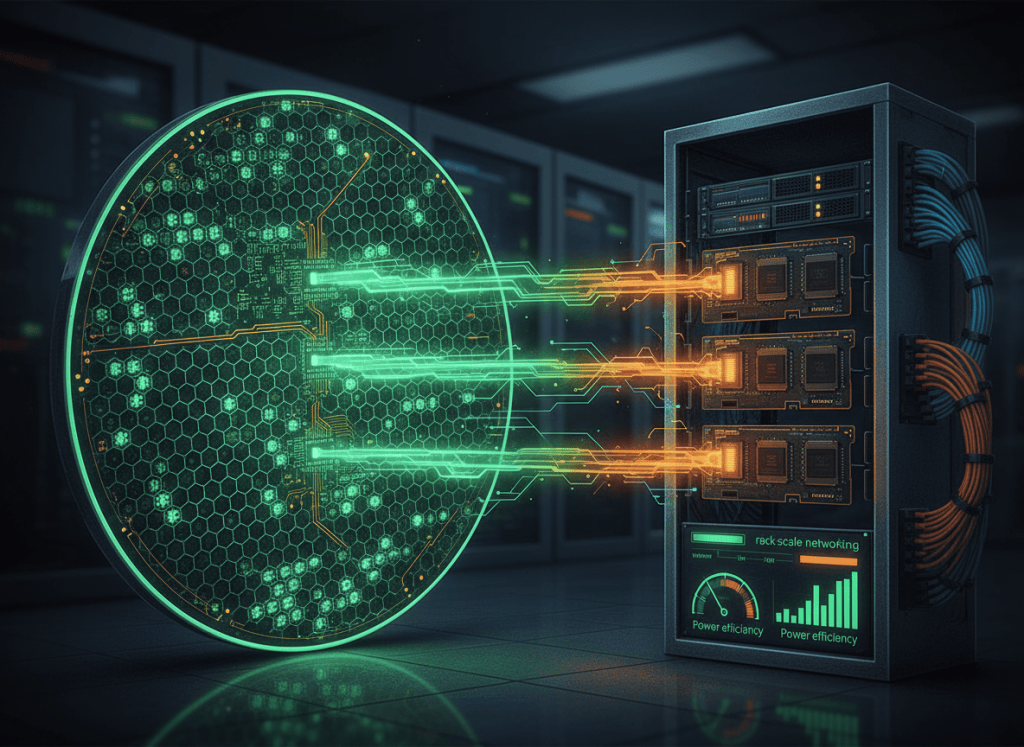
Cerebras Systems is getting a live market test of one of the boldest hardware bets in AI: replace racks of conventional accelerator chips with wafer-scale processors that keep far more compute and memory traffic on one enormous piece of silicon.
A new CNBC report says Cerebras shares fell nearly 20% for the week and reached their lowest level since the company’s May market debut. CNBC tied the pressure partly to Nvidia winning a key OpenAI inference workload and partly to the expiration of Cerebras’ post-IPO lockup period.
CNBC highlighted the move in a specific X post published October 2.
The technical bet is still radically different
Cerebras’ architecture starts from the idea that many AI bottlenecks are created by moving data between separate chips, memory pools and network fabrics. Instead of slicing a silicon wafer into hundreds of small dies, Cerebras keeps the wafer intact and turns nearly the entire surface into one giant processor.
That approach gives the company a very different scaling model from GPU clusters. A conventional GPU deployment expands by adding more accelerator packages and then tying them together with high-speed interconnects. Cerebras tries to collapse more of that communication onto the processor itself.
CS-4 pushes the wafer-scale idea into rack-scale inference
In its August CS-4 announcement, Cerebras said the new system combines three Wafer Scale Engines inside a rack-scale platform called Nexus.
The company claims CS-4 can deliver up to twice the speed of CS-3, up to 30 times more tokens per second per user than GPU-based alternatives, and up to 10 times more throughput per watt than its previous generation. Those are vendor claims rather than independent benchmark results, but they show where Cerebras believes its architectural advantage lives: inference latency, per-user throughput and energy efficiency.
The underlying WSE-3T design contains roughly four trillion transistors, 900,000 AI-optimized cores and tens of gigabytes of SRAM integrated directly on the processor. The point is to reduce the amount of time an AI workload spends waiting on off-chip movement.
Nvidia pressure matters because software is part of the moat
Cerebras is not only competing against Nvidia silicon. It is competing against CUDA, mature libraries, existing data-center deployment patterns and a huge installed base of engineers who already know how to tune GPU workloads.
That is why the OpenAI workload mentioned by CNBC matters beyond one customer win. Inference customers do not choose hardware from raw transistor counts alone. They care about model compatibility, latency, throughput, power, orchestration, networking and whether their software stack can move without breaking production.
BitcoinVersus.tech recently examined how AI coding agents are starting to automate CUDA kernel optimization. That trend can strengthen Nvidia’s software advantage because faster kernel search makes an already mature ecosystem even more productive.
Wafer-scale still attacks a real bottleneck
The counterargument is that scaling GPUs creates its own costs. More accelerator packages mean more networking, more protocol overhead, more cabling, more switching and more power spent moving data between devices.
That is the same infrastructure problem behind our report on Cerebras and Gimlet planning 100 MW of wafer-scale AI inference. If Cerebras can translate its single-wafer architecture into repeatable large-scale deployments, the payoff is not just chip speed. It is potentially a different balance between compute, networking and facility power.
We also previously looked at how Cerebras and AMD are attacking Nvidia’s AI infrastructure lead from different directions. AMD largely competes within the accelerator-cluster model. Cerebras is trying to change the physical scale of the processor itself.
The next test is deployment, not transistor count
Cerebras has already proven that wafer-scale processors can be manufactured and deployed. The harder question is whether enough customers want the architecture at production scale to overcome Nvidia’s ecosystem advantage.
That means the key metrics to watch are not only benchmark peaks. They are sustained tokens per second, tokens per watt, software portability, customer retention, system utilization and how quickly new models become available on the platform.
The stock move is therefore a useful signal of competitive pressure, but it does not settle the engineering question. Cerebras’ wafer-scale bet will ultimately be judged by whether its architecture can keep winning real workloads as Nvidia continues improving both hardware and software at the same time.
BitcoinVersus.Tech
Advertisement
Editor’s Note
We volunteer daily to ensure the credibility of the information on this platform is Verifiably True. If you would like to support to help further secure the integrity of our research initiatives, please donate here: 3C9o19EH5HSiwEPyCTmEKzxhNCbo2X6TTb
BitcoinVersus.tech is not a financial advisor. This media platform reports on financial subjects purely for informational purposes.


Leave a comment