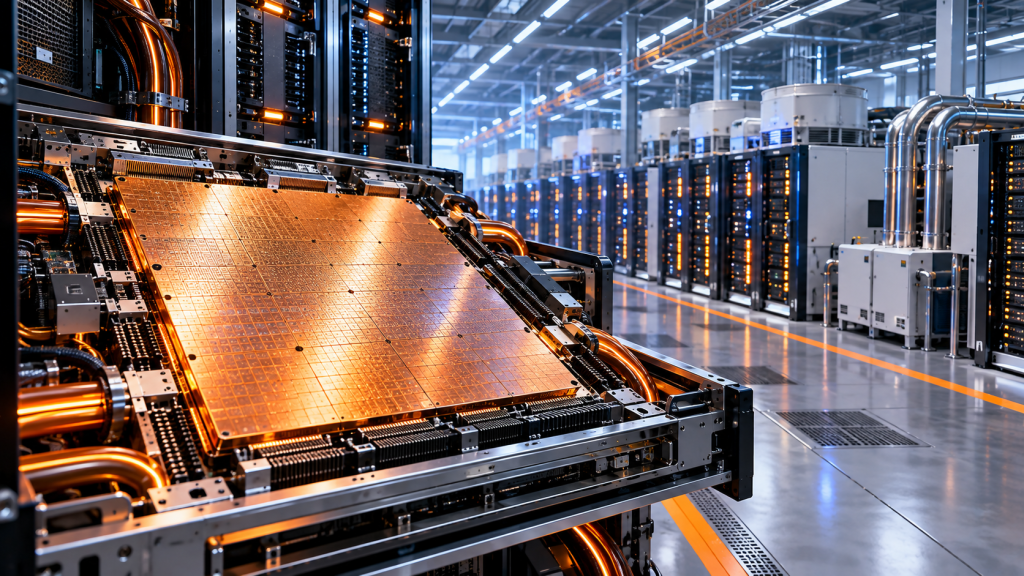
Cerebras Systems and Gimlet Labs plan to deploy roughly 100 megawatts of wafer-scale AI inference capacity, giving the young cloud company a large new pool of specialized compute built around Cerebras’ CS-4 systems.
The chipmaker says the agreement will make Gimlet a launch partner for CS-4, while independent reporting says the hardware is expected to roll out over roughly one to two years. Financial terms were not disclosed.
Gimlet Plans a 100 MW Cerebras Cloud Footprint
Gimlet Labs describes itself as an applied research lab building next-generation AI infrastructure. Its cloud platform is designed to schedule inference across different accelerator architectures instead of forcing every workload onto one type of silicon.
Gimlet made the scale of the Cerebras plan explicit in its announcement: 100 MW is planned, with its first Cerebras-powered data center expected later this year and claimed inference speeds of up to 3,000 tokens per second.
The announcement fits a broader shift toward purpose-built inference infrastructure. BitcoinVersus.tech recently covered Positron’s $875 million push into memory-first AI inference, Delos Data’s effort to attack AI’s interconnect bottleneck, and the earlier Cerebras and AMD infrastructure challenge to Nvidia.
CS-4 Puts Three Wafer-Scale Engines in One System
Cerebras introduced CS-4 in September as a rack-scale inference system built around three WSE-3 Turbo wafer-scale processors. The company claims CS-4 can deliver up to 30 times faster inference than conventional production GPU systems, although that performance figure is a vendor claim and will vary with model, workload and serving configuration.
Cerebras’ own English-language overview below explains the CS-4 architecture and WSE-3 Turbo. The video is hosted on the company’s established YouTube channel, which has about 48,000 subscribers, and its live watch page exposes YouTube’s standard external player.
Why the 100 MW Number Matters
A 100 MW deployment is not simply a chip order. At full buildout, it implies data-center-scale electrical infrastructure, cooling, networking and operations wrapped around the accelerator systems. Gimlet will operate and maintain the Cerebras hardware after deployment, according to Reuters.
Gimlet CEO Zain Asgar told Reuters that low-latency inference matters for workloads including cybersecurity, voice applications and financial analysis. Those use cases can be unusually sensitive to response time because the value of an answer can fall quickly when model output arrives too slowly.
The first CS-4 capacity is expected to become available through Gimlet Cloud in 2027. That makes the deal a forward deployment rather than 100 MW of capacity already online today, an important distinction when comparing announced AI infrastructure with operating compute.
Inference Competition Is Moving Beyond GPUs
The agreement gives Cerebras another route to customers who want fast model serving without owning the underlying systems. For Gimlet, the partnership adds wafer-scale silicon to a cloud strategy built around heterogeneous compute.
If the full 100 MW is delivered, the deployment would also become a substantial real-world test of wafer-scale inference at data-center scale. The key metrics will be more than headline tokens per second: utilization, reliability, power efficiency, model support and cost per served token will determine how competitive the platform becomes.
BitcoinVersus.Tech Editor’s Note
Support independent technology reporting: BTC donations may be sent to 3C9o19EH5HSiwEPyCTmEKzxhNCbo2X6TTb.
Follow BitcoinVersus.tech on X/Twitter for AI hardware, semiconductors, Bitcoin mining and data-center reporting.
Disclaimer: BitcoinVersus.tech is not a financial advisor. This media platform reports on financial subjects purely for informational purposes.


Leave a comment