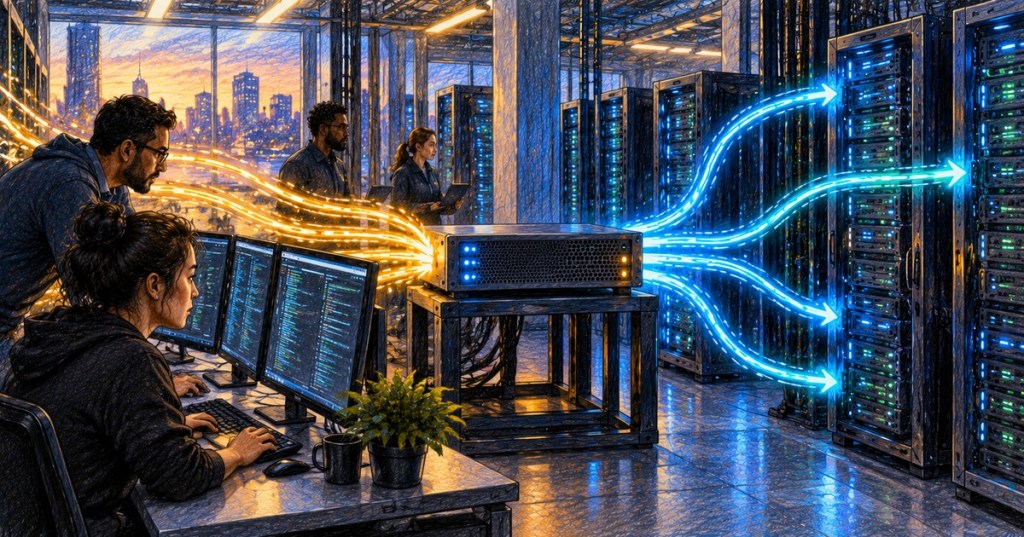
A load balancer distributes incoming traffic across multiple servers instead of sending every request to one machine. Its basic job is simple: accept traffic, decide which healthy backend should handle it, and forward the request there.
That one function helps websites and applications scale beyond a single server. It can also improve availability because traffic can be redirected when one backend becomes unhealthy.
Why Load Balancers Exist
Imagine an application running on one web server. As traffic grows, that server eventually has to process more connections, requests, memory use, and application work. One solution is vertical scaling: make that server larger. Another is horizontal scaling: run the application on several servers.
Once several servers can answer the same application request, something has to decide which server receives each new request. That is where the load balancer sits.
Cloudflare’s load-balancing documentation describes the core idea as spreading traffic across multiple servers so no single server carries all of the work.
The Basic Traffic Path
The simplest path looks like this: client → load balancer → backend server. A user connects to the public application address. The load balancer receives the request and chooses one server from a group of available backends.
To the user, the application can still look like one service even though several servers are working behind it. This is closely related to the role of a reverse proxy, and some products can perform both jobs.
How Does It Choose a Server?
Load balancers can use several traffic-distribution methods. The exact names vary by product, but common approaches include round robin, least connections, weighted distribution, hashing, geographic steering, and performance-based routing.
- Round robin: requests rotate across available servers.
- Least connections: traffic goes toward the server handling fewer active connections.
- Weighted: larger or faster servers can intentionally receive more traffic.
- Hash-based: information from the connection can help consistently choose a backend.
- Location or performance: distributed systems can steer users toward nearby or faster infrastructure.
Health Checks Matter
Distributing traffic only works if the chosen servers are actually healthy. Load balancers therefore commonly perform health checks against their backends. A check may verify that a TCP port accepts connections, that an HTTP endpoint returns the expected status, or that a more application-specific test succeeds.
If a server fails its health checks, the load balancer can temporarily remove it from normal traffic. When the server becomes healthy again, it can be added back.
NGINX documents this model in its HTTP load-balancing guide, including upstream server groups, balancing methods, weights, and server availability.
Load Balancing Can Improve Availability
A load balancer does not prevent servers from failing. What it can do is reduce how much a single server failure affects users. If five servers run the same application and one becomes unavailable, the load balancer can continue sending new traffic toward the remaining healthy servers.
This is one reason load balancing is common in data centers and cloud environments. It becomes part of a larger high-availability design rather than a guarantee of availability by itself.
What Is Session Affinity?
Some applications work best when the same user keeps reaching the same backend for a period of time. That behavior is commonly called session affinity or a sticky session.
Sticky sessions can simplify some application designs, but they also reduce how freely traffic can move between servers. Modern applications often try to keep session state in shared systems so any healthy backend can serve the next request.
Load Balancer vs. Reverse Proxy
The two roles overlap, but the emphasis is different. A reverse proxy represents backend servers and accepts requests for them. A load balancer specifically distributes traffic across multiple destinations.
One product can do both. NGINX, HAProxy, cloud application load balancers, and other platforms can receive requests as a reverse proxy while also selecting among multiple upstream servers.
A forward proxy is different: it acts for clients rather than for the servers receiving the application traffic.
Layer 4 vs. Layer 7 Load Balancing
A Layer 4 load balancer makes decisions using transport-level information such as IP addresses and TCP or UDP ports. A Layer 7 load balancer understands application-layer protocols such as HTTP and can make routing decisions using hostnames, paths, headers, cookies, or other request details.
That distinction affects performance, flexibility, observability, and how much application information the load balancer needs to understand.
DNS Can Also Distribute Traffic
Traffic distribution does not always happen through an inline appliance or software proxy. DNS can return different addresses for the same service, and global systems can steer users between regions or data centers before a connection is established.
That is different from an inline load balancer because DNS answers can be cached and the traffic may then flow directly to the selected address. BitcoinVersus.Tech’s browser-to-website walkthrough explains where DNS fits into the connection process.
Common Places You See Load Balancing
- Public websites running on several web servers.
- APIs distributed across application instances.
- Cloud services operating across availability zones or regions.
- Kubernetes and container environments.
- Database read replicas and some clustered database systems.
- Enterprise applications where one frontend address represents several backend systems.
The Easy Way to Remember It
A load balancer is the traffic coordinator in front of a group of servers. It receives work, checks which backends are available, and sends each request toward an appropriate destination.
The point is not simply to make every server equally busy. The larger goal is to keep an application responsive, scalable, and available while traffic and server health change.
Editor’s Note
A load balancer is one component of a resilient architecture. High availability also depends on healthy backend servers, redundant networking, working DNS, application design, monitoring, and enough spare capacity to survive failures.
We volunteer daily to improve the credibility of the information on this platform. If you would like to support the research, please donate here: 3C9o19EH5HSiwEPyCTmEKzxhNCbo2X6TTb
BitcoinVersus.tech is not a financial advisor. This media platform reports on technical and financial subjects purely for informational purposes.


Leave a Reply