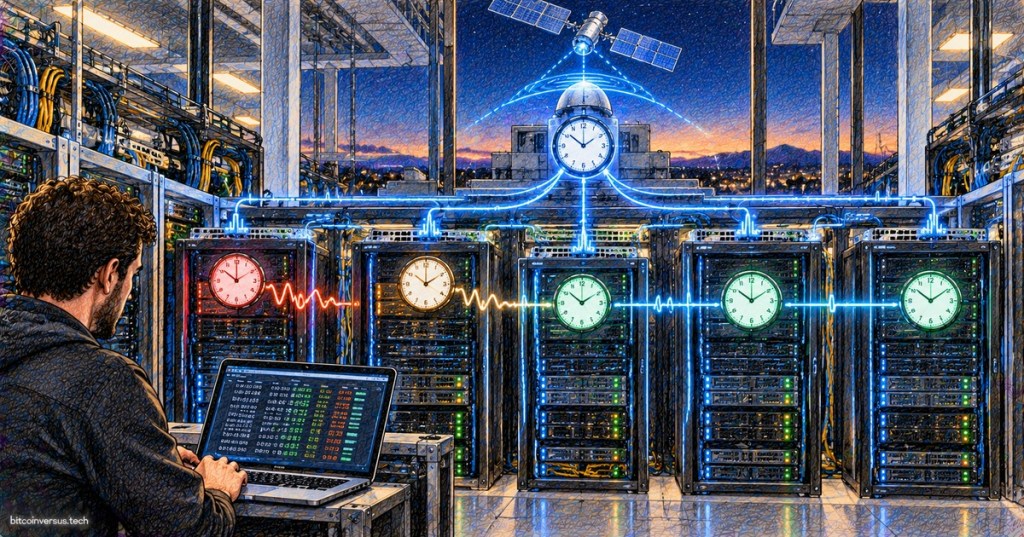
Network Time Protocol, or NTP, is the system that keeps computers, switches, servers, virtual machines, cameras, security systems, and other networked devices agreeing on what time it is. That sounds simple until two machines disagree by several seconds and suddenly log files no longer line up, authentication fails, certificates appear invalid, scheduled jobs fire at the wrong time, and troubleshooting turns into guesswork.
NTP is defined by the Internet Engineering Task Force and is widely used to synchronize computer clocks to a common reference, usually Coordinated Universal Time, or UTC. RFC 5905 defines NTP version 4, while the Network Time Foundation maintains resources around NTP implementations and security.
Why Accurate Time Matters More Than It Looks
Most people think of a computer clock as a convenience for displaying the time in the corner of a screen. In infrastructure, time is part of the system itself. Every event written to a log carries a timestamp. Every security investigation depends on ordering events correctly. Databases, monitoring platforms, backups, distributed applications, and authentication systems all assume clocks are reasonably aligned.
Red Hat’s time-synchronization documentation specifically notes that consistent time improves log traceability and that protocols such as Kerberos rely on timestamps to prevent replay attacks. Even TLS certificates depend on a machine understanding whether the current time falls inside a certificate’s validity window.
Computer Clocks Drift
A computer does not magically know the exact time forever. Its local oscillator drifts. Temperature, hardware tolerances, power states, virtualization, and normal clock error can gradually move a system away from accurate time.
That means setting a clock correctly once is not enough. NTP continuously compares the local clock against trusted time sources and disciplines the system clock so the error stays small rather than growing indefinitely.
NTP Uses a Hierarchy Called Stratum
NTP organizes time sources into layers called strata. A reference clock such as an atomic clock, GPS receiver, or other high-accuracy source is conceptually referred to as stratum 0. It is not normally an ordinary network server.
A server directly synchronized to that reference is stratum 1. A device synchronized to a stratum 1 source is typically stratum 2, and so on. The number describes how many synchronization steps separate a device from a primary reference source; it is not simply a quality score where every stratum 2 source is automatically better than every stratum 3 source.
Large organizations often run internal time servers rather than allowing every switch and server to contact arbitrary internet time sources. Internal servers synchronize upstream, then provide consistent time to local infrastructure.
NTP Usually Uses UDP Port 123
NTP traditionally uses UDP port 123. That fits the protocol well because NTP exchanges small timing messages and does not need a long-lived reliable byte stream. BitcoinVersus.Tech’s TCP and UDP overview explains the broader transport-layer difference.
RFC 5905 notes that reliable retransmission can actually make timing measurements worse because retries add delay. For time synchronization, knowing when a packet was sent and received matters more than guaranteeing that every individual packet eventually arrives.
NTP Measures Both Delay and Clock Offset
An NTP exchange contains timestamps that let the client estimate two important things: how long the network path took and how far the local clock appears to be from the server’s clock. NTP does not simply copy the remote time and assume the network delay was zero.
That distinction is critical. If a packet takes 40 milliseconds to travel across the network, blindly setting the local clock to the timestamp inside that packet would immediately introduce error. NTP compares multiple timestamps and observations to estimate offset and delay, then selects and filters time sources before adjusting the local clock.
NTP Does Not Normally Yank the Clock Around Constantly
Small clock errors are commonly corrected gradually. This process is often described as slewing the clock: the system slightly speeds up or slows down its software timekeeping until the error disappears. Large errors, especially during startup, may sometimes be corrected by stepping the clock directly depending on the implementation and configuration.
Gradual correction matters because abruptly moving time backward can confuse applications that assume timestamps always increase. Databases, logs, monitoring software, schedulers, and distributed systems can behave unexpectedly if the wall clock jumps.
Linux Commonly Uses chrony
Modern Red Hat Enterprise Linux uses chrony as its NTP implementation. The suite includes the chronyd daemon, which disciplines the system clock, and the chronyc command-line utility, which administrators can use to inspect synchronization state and sources.
Red Hat notes that chrony is designed to work well across changing network conditions, systems that are not continuously powered, virtual machines, temperature changes, and congested links. Those characteristics matter because a virtual machine may experience very different clock behavior from a physical server with a stable oscillator.
Common read-only checks include chronyc tracking to inspect the local clock state and chronyc sources to inspect upstream time sources. On systemd-based Linux systems, timedatectl can also show whether network time synchronization is enabled and whether the system currently considers itself synchronized.
DNS Can Break NTP Before NTP Even Starts
Administrators often configure time sources using hostnames rather than raw IP addresses. That means a broken DNS path can look like an NTP failure because the client cannot resolve the server name.
The correct troubleshooting order matters. Verify basic IP connectivity, name resolution, firewall policy, UDP 123 reachability, the NTP daemon, upstream sources, and finally the clock offset. Jumping directly to reinstalling chrony when DNS is broken wastes time.
Time Zones Are Not the Same as Time Synchronization
A system can have perfectly synchronized time and still display a different local clock than another machine because of time-zone configuration. NTP synchronizes the underlying notion of time. The operating system then applies a local time-zone rule for human-readable display.
This is why infrastructure teams often store logs in UTC even when engineers work across several time zones. UTC makes event correlation easier because the raw timestamps do not shift with daylight-saving changes or geographic location.
Why Logs Fall Apart Without NTP
Imagine a login request passes through a load balancer, application server, database, firewall, and identity server. If every device disagrees by 30 seconds, the same transaction appears to happen in the wrong order across the logs.
That makes root-cause analysis much harder. A firewall might appear to block a session before the user attempted it. A server crash might appear to happen after its recovery. A security event might look disconnected from the authentication attempt that caused it. Synchronizing clocks turns distributed logs into one coherent timeline.
NTP Matters for Kerberos Authentication
Kerberos uses time-limited tickets and timestamps as part of its defense against replay attacks. If a client and authentication server disagree too much about the current time, otherwise valid authentication can fail.
This is one reason time synchronization is foundational in Active Directory and other Kerberos-based environments. A user may report “the password is correct but login fails,” while the real problem is a system clock that drifted outside the allowed tolerance.
NTP Matters for TLS and Certificates
HTTPS and TLS certificates include validity periods. A machine whose clock is badly wrong may believe a valid certificate has not started yet or has already expired.
This is especially common on systems that lose their real-time clock after a battery failure, embedded devices that boot with an old date, or freshly restored virtual machines. Correct time becomes a prerequisite for establishing secure connections.
Multiple Time Sources Improve Resilience
Production systems should generally avoid depending on one time server. NTP clients can query multiple upstream sources, compare them, reject outliers, and select suitable candidates. That reduces the chance that one failed, unreachable, or incorrect server causes the entire environment to drift.
The exact source-selection algorithms are more sophisticated than simply averaging every response. NTP is designed to measure source quality, delay, dispersion, and consistency before disciplining the local clock.
NTP and PTP Solve Different Accuracy Problems
NTP is excellent for general-purpose infrastructure, but some systems need much tighter synchronization. Financial trading, telecom, industrial automation, broadcast, measurement systems, and certain data-center applications may use Precision Time Protocol, or PTP, when microsecond- or sub-microsecond-level synchronization is required.
PTP can use hardware timestamping inside network interface cards and switches so software scheduling delays contribute less error. NTP remains simpler and more widely deployed for ordinary server, workstation, switch, and application timing.
A Simple NTP Troubleshooting Order
- Check the system’s current date, time, and time zone.
- Confirm basic network connectivity to the intended time source.
- If a hostname is used, verify DNS resolution.
- Confirm the NTP service or chronyd daemon is running.
- Verify firewall policy permits the required NTP traffic.
- Inspect the configured upstream sources.
- Check whether the client has selected a valid synchronization source.
- Measure offset, delay, and synchronization status.
- Look for virtualization, hardware-clock, suspend/resume, or temperature-related drift if the error keeps returning.
- Compare multiple hosts to determine whether the problem is one machine or the upstream time infrastructure.
The Simple Way to Remember NTP
NTP does not merely tell a computer what time it is. It continuously helps the computer estimate how wrong its own clock is and correct that error using trusted network time sources.
That makes NTP one of those invisible protocols that becomes extremely visible when it stops working. When clocks disagree, logs, authentication, certificates, monitoring, automation, and troubleshooting can all start failing at once.
References
- RFC 5905 — Network Time Protocol Version 4
- Network Time Foundation — NTP Support
- Red Hat Enterprise Linux — Configuring Time Synchronization
BitcoinVersus.Tech
Advertisement
BitcoinVersus.Tech covers networking, Linux, servers, data centers, security, Bitcoin mining, semiconductors, and the infrastructure behind modern computing.
Editor’s Note
NTP implementation details, daemon defaults, source-selection behavior, authentication, and clock-step policies vary by operating system and software release. Follow the documentation for the exact platform before changing production time infrastructure.
We volunteer daily to help keep the information on this platform verifiably accurate. Support our independent research through the support options available on BitcoinVersus.Tech.
BitcoinVersus.tech is not a financial advisor. Content is provided for informational purposes.


Leave a comment