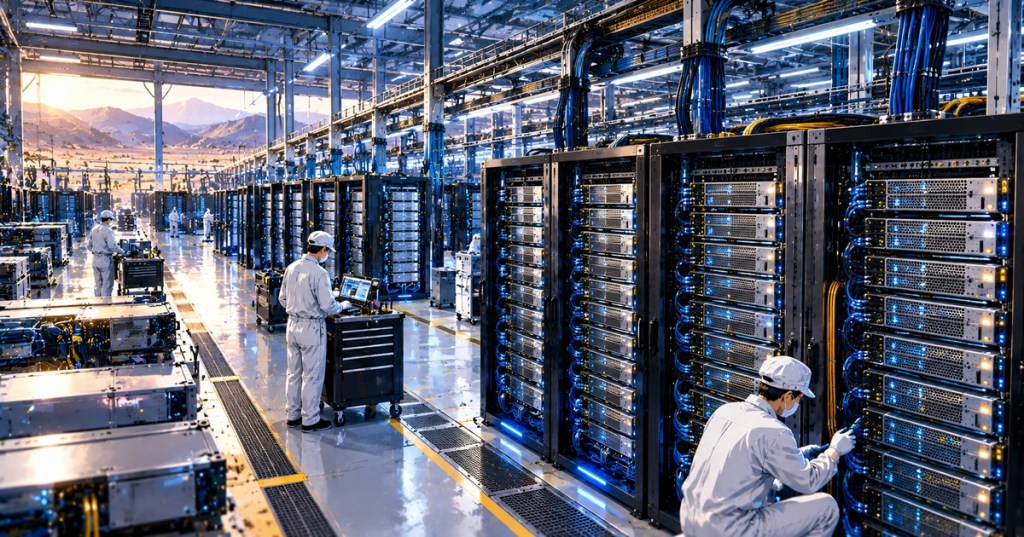
d-Matrix launched Squadron on October 12, a multi-rack AI inference system that scales to 16 racks and 1,024 Corsair XPUs. The company says Squadron is already running in its Arizona data center and is now shipping to priority customers.
The unusual part is cooling: Squadron is air-cooled, not liquid-cooled. d-Matrix says that lets customers deploy it inside existing industry-standard data centers rather than rebuild facilities around new cooling infrastructure. The system combines Corsair XPUs, JetStream NICs and Aviator software, with Arista, Broadcom and Supermicro named as development partners.
Company-reported performance: d-Matrix says a heterogeneous setup pairing Squadron with GPU servers reached 845 tokens per second per user and 20,415 tokens per second across 64 concurrent users using Attention-FFN Disaggregation. Those figures come from d-Matrix’s own demonstration and are not yet an independent industry benchmark.
The broader shift is important: AI infrastructure is starting to split workloads across different accelerators instead of forcing every task onto one GPU architecture. RuntimeWire notes that Squadron moves d-Matrix from selling accelerators toward complete data-center infrastructure.
Related BitcoinVersus.Tech coverage: What Is CUDA? · Flex Says Its AI Modules Can Cut Deployment Time by 50% · Lumentum Says AI Optics Are Sold Out Through Early 2029.
BitcoinVersus.Tech Editor’s Note:
We volunteer daily to ensure the credibility of the information on this platform is Verifiably True. If you would like to support to help further secure the integrity of our research initiatives, please donate using the QR code provided


Leave a Reply