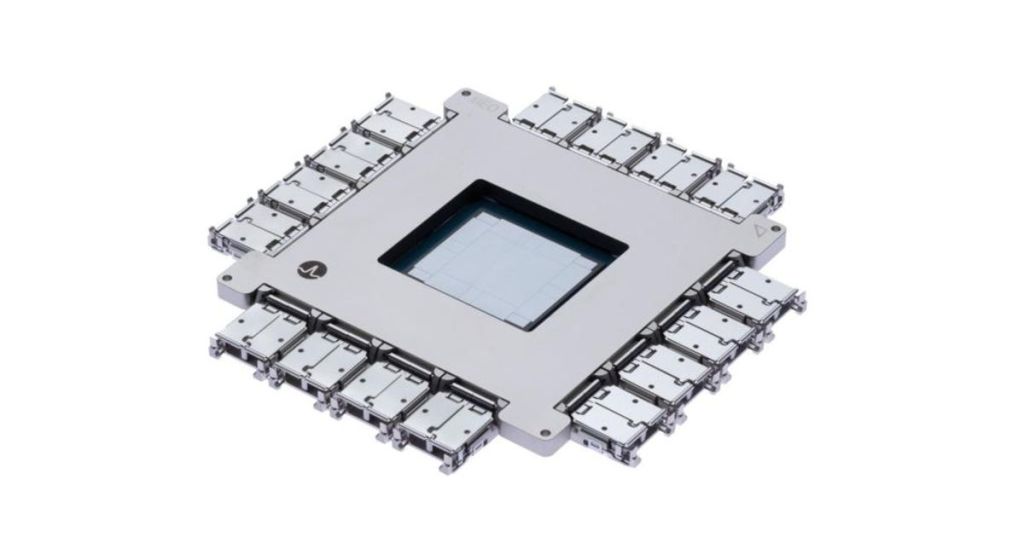
Broadcom is bringing its latest AI networking stack to the 2026 Open Compute Project Global Summit, putting 102.4-terabit-per-second Ethernet switching, 800G network interface cards and co-packaged optics in the same rack-scale conversation. The company says its OCP 2026 showcase will include Tomahawk 6, Tomahawk Ultra, Jericho 4, Thor Ultra 800G and Thor 2 400G NICs, plus its third-generation TH6-Davisson co-packaged-optics platform.
The hardware is not one single new product launch. It is a demonstration of how Broadcom wants Ethernet to stretch across the entire AI cluster: inside a rack, between racks and eventually between large computing sites.
The centerpiece is still Tomahawk 6
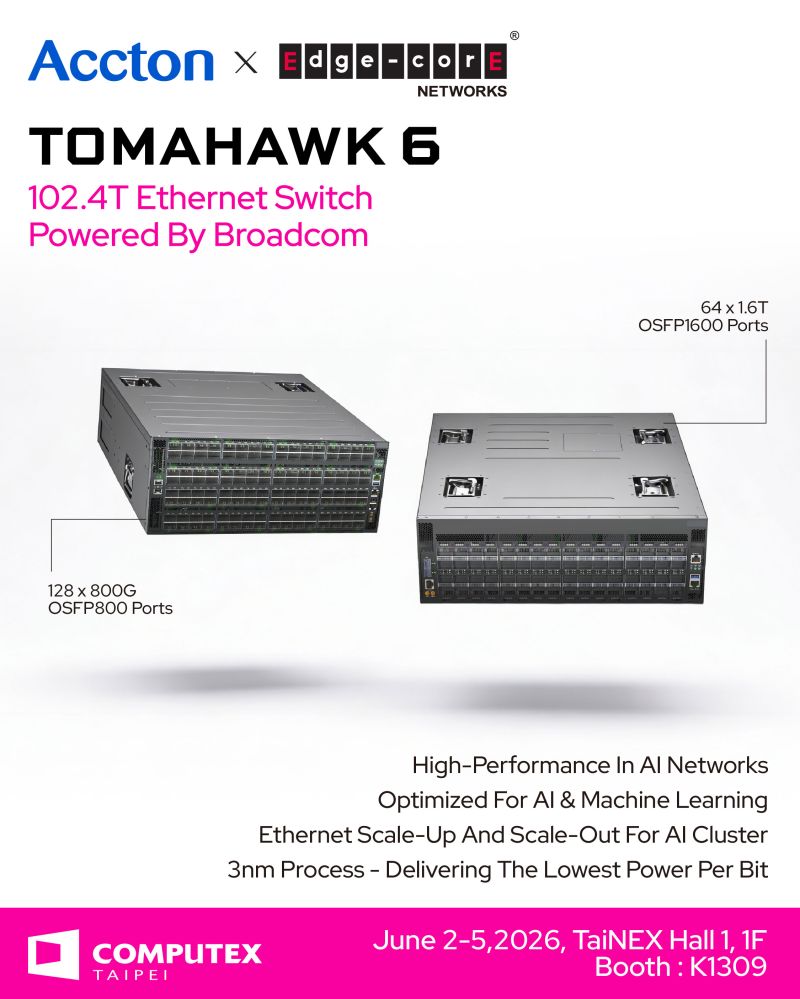
Tomahawk 6 is Broadcom’s 102.4 Tb/s Ethernet switch family. At that aggregate bandwidth, one switch ASIC can expose hundreds of extremely fast electrical lanes and help flatten network designs that would otherwise need more switching stages. Broadcom says a Tomahawk 6 design can connect as many as 512 accelerators in a single-hop scale-up domain, while two-tier scale-out designs can reach beyond 100,000 accelerators at 200 Gb/s per link.
That matters because an AI cluster is not just a collection of GPUs or other accelerators. The accelerators constantly exchange parameters, gradients, activations and other data. When the interconnect cannot keep up, expensive compute can sit idle waiting for traffic. The basic idea is familiar from a conventional network switch, but the scale and traffic patterns are far more demanding.
800G NICs move the bottleneck toward the server
On the endpoint side, Broadcom is highlighting Thor Ultra, an 800G AI Ethernet network interface card, alongside its 400G Thor 2 family. The NIC is the hardware boundary between a server or accelerator node and the network fabric. Increasing switch capacity without increasing endpoint bandwidth would simply move the bottleneck from the fabric into the server.
The broader industry is already pushing beyond today’s common 400G links. BitcoinVersus has tracked 1.6T Ethernet moving toward deployment and 3.2T-class optical roadmaps. Broadcom’s OCP lineup fits that same trend: more bandwidth per device, fewer network stages and tighter coordination between switches, NICs and optics.
Co-packaged optics attacks the electrical-distance problem
TH6-Davisson adds another piece: co-packaged optics, or CPO. Traditional high-speed switches place removable optical modules at the front of a chassis and carry very fast electrical signals across the circuit board between the switch ASIC and those modules. As lane rates rise, that electrical path becomes harder to drive efficiently and reliably.
CPO moves optical engines much closer to the switching silicon. The goal is to shorten high-speed electrical paths, reduce signal loss and lower the amount of power spent moving bits before they ever reach the fiber. BitcoinVersus has already covered Micas moving CPO switches into manufacturing and Ciena’s 6.4T CPO roadmap, signs that optical integration is moving from lab discussion toward deployable infrastructure.
Scale-up, scale-out and scale-across are becoming separate design problems
Broadcom is organizing its message around three directions of growth. Scale-up connects accelerators inside a tightly coupled computing domain. Scale-out connects many servers or accelerator groups into a larger cluster. Scale-across extends that idea between clusters or data centers when one building cannot provide enough power, cooling or physical space.
That last category is increasingly important. A modern AI build can become constrained by megawatts and gigawatts before it runs out of theoretical compute demand. The network therefore has to keep useful bandwidth and predictable latency across larger physical distances. Open approaches are also gaining attention; BitcoinVersus recently covered an open token-fabric proposal for mixed AI accelerators, another example of the industry trying to avoid making every large cluster a closed island.
Why OCP is the right stage for this hardware
The 2026 OCP Global Summit runs October 12–15 in San Jose and is built around open data-center hardware and software. Broadcom says more than 15 partners will demonstrate pieces of its AI networking stack, including Tomahawk 6 systems, liquid-cooled switching and TH6-Davisson CPO platforms.
That partner ecosystem may be more important than any single bandwidth number. A 102.4 Tb/s switch ASIC is useful only if system vendors can turn it into reliable chassis, optics vendors can feed it, NICs can drive traffic into it, software can control congestion and operators can service the whole thing at scale.
The practical takeaway is that AI infrastructure is becoming a networking problem as much as a compute problem. Faster accelerators still matter, but their value increasingly depends on how efficiently data can move between them. Broadcom’s OCP 2026 showcase is an argument that open Ethernet—backed by faster switches, 800G NICs and optics placed closer to the silicon—can remain the common fabric as clusters grow from racks to buildings and beyond.
Editor’s note: Product capabilities and scaling claims in this article are based on vendor specifications and should be evaluated in the context of the deployed network topology, software stack, optics and workload.
Disclaimer: BitcoinVersus.Tech publishes technology news and analysis for informational purposes. Company statements and product specifications may change as hardware moves through validation and deployment.


Leave a Reply