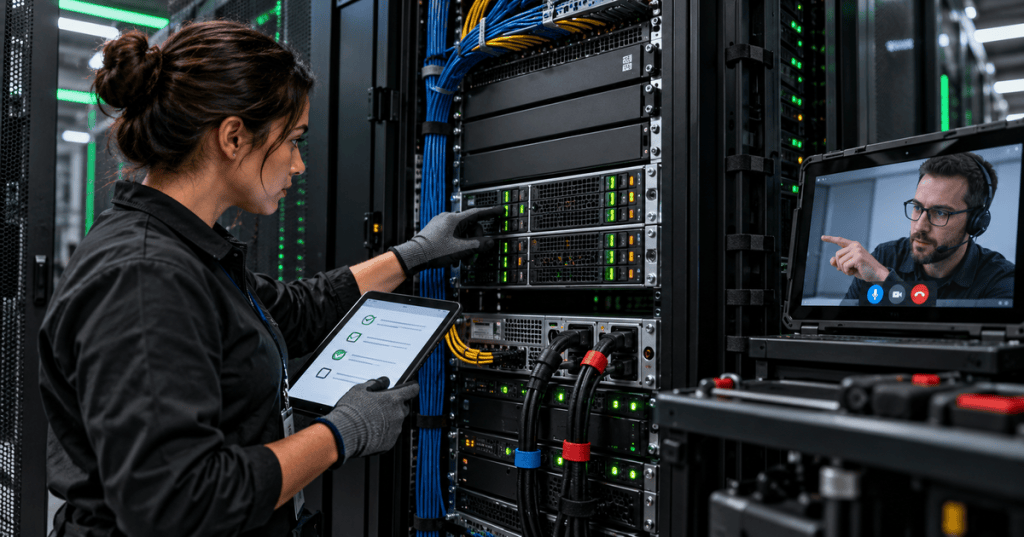
Remote hands is the controlled use of an on-site data center technician to perform physical work for an engineer, customer, or operations team that may be somewhere else. The hands-on task might be as small as reading an LED or tracing a cable, or as consequential as replacing a power supply, moving a patch cord, power-cycling a production device, or removing hardware. The technical action matters, but the larger skill is executing exactly the authorized change and proving what happened.
This lesson follows OSDCTC.010: Server FRU Replacement and Change Verification. That lesson focused on replacing a field-replaceable unit correctly. OSDCTC.011 expands the scope to the operational process around the work: ticket identity, authorization, work instructions, MOPs, maintenance windows, checkpoints, stop conditions, remote communication, evidence capture, rollback, and closeout.
Equinix explains how Smart Hands technicians perform physical data center tasks for customers who are not on site.
Elementary Overview
A remote engineer can see logs, dashboards, configuration, and telemetry, but cannot physically touch a cable, observe a chassis LED from a different angle, reseat a component, verify a label, or inspect a rack for an obstruction. Remote hands closes that gap by placing a qualified technician at the equipment while preserving authorization and traceability.
Equinix describes Smart Hands as on-site operational support for installation, troubleshooting, cabling, equipment handling, inventory, visual verification, and similar physical tasks. The principle is broader than any one provider: the on-site technician becomes the remote team’s physical interface to the hardware.
The technician must therefore be precise. “Move the blue cable” is not enough. A valid instruction should identify the correct site, room or cage, rack, U position, device, port, cable label, source and destination, expected state, timing, and verification method. If any of those details conflict with what is physically present, the technician stops and escalates instead of improvising.
Learning Objectives
- Explain the role of remote hands and Smart Hands in data center operations.
- Distinguish a work ticket, SOP, MOP, and EOP.
- Verify the exact asset, location, component, and authorization before touching equipment.
- Recognize maintenance windows, hold points, stop conditions, and rollback requirements.
- Communicate clearly with a remote engineer without substituting assumptions for instructions.
- Use pre-change and post-change evidence to prove the final state.
- Know when a technician must stop work and escalate instead of continuing.
- Close a change with timestamps, evidence, asset updates, and a verified service result.
The Ticket Is the Authorization Boundary
A remote-hands request should identify what work is approved. The ticket is not merely an administrative record; it defines the boundary of the technician’s authority. A request to inspect a device does not automatically authorize a reboot. A request to replace a failed PSU does not automatically authorize moving the surviving PSU to another feed. A request to patch one network port does not authorize cleaning up neighboring cabling.
Before work begins, reconcile the ticket against the physical environment. Confirm the site, room, cage or suite, cabinet, rack name, U position, hostname or asset tag, chassis serial number, component identifier, source port, destination port, cable label, and any maintenance-window timing. This is the same physical-discipline principle used in OSDCTC.004: Server Rack-and-Stack and OSDCTC.003: Structured Cabling and Patch Panels.
Equinix demonstrates order and ticket history, illustrating why the work record and status trail are part of remote-hands execution.
SOP, MOP, and EOP Are Different Documents
SOP means Standard Operating Procedure. It covers a routine, repeatable operational process. MOP means Method of Procedure. It describes a specific planned change or maintenance task in controlled steps. EOP means Emergency Operating Procedure. It governs abnormal or emergency conditions where the priority is safe stabilization and recovery.
Uptime Institute’s guidance on MOPs emphasizes detailed steps, expected results, prerequisites, safety requirements, version control, approvals, and back-out planning. NIST’s SP 800-128 describes configuration change control as a documented process that requests, analyzes, approves, implements, and verifies changes. Those ideas apply directly to technician work because a physical change can alter the same production system that software and configuration controls are meant to protect.
A recent data center community discussion shows how operators use SOPs, MOPs, and EOPs in real facilities and why local terminology can vary by organization.
A Good MOP Defines More Than Steps
A technician should be able to answer five questions before executing a planned change: What exactly am I touching? Why is this change approved? What should happen after each important step? What condition tells me to stop? How do I return to the previous safe state if the change fails?
- Scope: exact equipment and task.
- Prerequisites: approvals, access, spares, tools, software or remote staff readiness.
- Safety: ESD controls, PPE, electrical boundaries, lifting rules, LOTO or other site-specific controls when required.
- Initial state: what must be healthy before work starts.
- Procedure: one unambiguous action at a time.
- Expected result: LED, alarm, link state, telemetry, inventory, or service behavior expected after a step.
- Hold point: a required confirmation before the next action.
- Abort criteria: conditions that immediately stop the procedure.
- Rollback: steps required to restore the prior known-good state when possible.
- Verification: evidence that the change produced the intended result.
- Closeout: timestamps, serial numbers, photos, logs, ticket notes, asset updates, and final approval.
A strong technician does not silently “fix” a bad MOP while executing it. If a step does not match the physical system, stop at the mismatch, preserve the current state, and escalate. The procedure can then be corrected under change control.
Remote Communication Must Be Closed-Loop
Remote-hands work often involves a person on site and another person watching telemetry or directing the change remotely. Closed-loop communication reduces ambiguity. The remote engineer gives one specific instruction. The technician repeats back the important identifiers and intended action. The remote engineer confirms. The technician performs the action, states what physically changed, and reports the observed result.
For example: “Confirm rack DC-17, U32, server dc17-app-04, left PSU labeled PSU1, amber fault LED.” After the technician reads the same identity back and the remote engineer confirms, the action can proceed. This is safer than conversational shorthand such as “pull the bad supply.”
Video can be useful when labels, connector positions, indicators, or physical obstructions are difficult to describe. Equinix’s Smart Hands Video documentation is an example of live visual collaboration between the customer and the on-site technician. Video does not replace the ticket or authorization boundary; it improves shared situational awareness.
Use Maintenance Windows and Hold Points
A maintenance window defines when an approved activity may occur. It does not mean every step should begin immediately at the opening time. Prechecks come first. Confirm that dependent teams are ready, monitoring is active, backups or redundancy are healthy, the correct spare is present, access is available, and the rollback path is still valid.
A hold point is a deliberate pause that requires verification or approval. Examples include waiting for the remote engineer to confirm traffic has drained before pulling a cable, confirming a redundant feed is carrying load before removing a PSU, or waiting for a storage array to report the correct failed drive before opening a carrier. Hold points prevent an error in one step from being amplified by the next.
Pre-Change Evidence Creates a Baseline
Before changing anything, capture enough evidence to describe the starting state. Depending on the task, that may include photos of rack position and cabling, BMC health, switch-port state, interface counters, PSU status, drive status, alarm text, temperature, serial numbers, firmware inventory, cable labels, and application or service checks provided by the remote team.
The point is not to collect random screenshots. Evidence should answer a later question: What was true before the technician touched the system? The post-change evidence should answer the paired question: What is true now, and does it prove the requested result?
Physical Touch Discipline
Remote-hands technicians should minimize the physical failure domain. Touch only the authorized component. Preserve cable routing, power-feed separation, airflow, blanking panels, fiber bend radius, strain relief, labels, and neighboring equipment. If a work instruction requires moving unrelated hardware to gain access, that additional action must be authorized before it happens.
For hardware replacement, follow the platform-specific service rules from OSDCTC.010. For network-side validation after a cable or NIC change, repeat the checks from OSDCTC.008: Server Network Configuration and Validation. For power changes, preserve the A/B-feed principles from OSDCTC.002: Rack Power Distribution.
Stop Conditions Are a Technician Skill
The ability to stop is part of professional execution. Work should pause when the physical environment does not match the ticket, labels are missing or contradictory, the asset identity cannot be proven, a supposedly redundant path is already degraded, the required spare is wrong, the expected result does not occur, a new alarm appears, a maintenance window expires, or the remote engineer cannot confirm the next step.
Do not “try one more thing” merely because the technician is already standing at the rack. Every unplanned action increases the change surface. Escalation preserves evidence and gives the owning team a chance to reassess risk before the system moves farther from its known state.
Equinix demonstrates enhanced order entry and order status, reinforcing the connection between the requested work, live status, and controlled completion.
Rollback Is Not the Same as Troubleshooting
A rollback plan describes how to return to the prior known-good state when the planned change fails and reversal is technically possible. It is not permission to invent a new troubleshooting path. If a patch move fails, rollback may mean restoring the original cable and verifying the original link. If a replacement adapter fails to initialize, rollback may mean reinstalling the original known-good adapter if the procedure authorizes that action.
Some changes are not fully reversible. A failed drive may already be removed from an array, a firmware update may alter persistent state, or a destructive sanitization action may be irreversible. The MOP must identify those boundaries before work begins. The technician cannot create reversibility after the fact.
Change Control and Reliability
OSDCTC technicians execute work at the physical layer, while the engineering pathway examines broader availability and failure-domain design. OSDCEC.007: Data Center Reliability Engineering explains how change control fits with availability, MTBF, MTTR, FMEA, and RCA. The technician-level translation is straightforward: approved work must preserve the intended redundancy, expose as little live infrastructure as possible, and leave evidence strong enough to reconstruct what happened.
Post-Change Verification
- Confirm the physical task is complete and no unrelated equipment was disturbed.
- Verify the requested component, cable, or device is in the intended final position.
- Check expected LEDs, alarms, BMC state, link state, power state, inventory, or other device health.
- Ask the remote engineer or service owner to verify the logical or application-level result when that verification is outside the on-site technician’s view.
- Confirm redundant paths, feeds, links, fans, PSUs, or other protection mechanisms have returned to the required state.
- Check for new alarms or unexpected telemetry changes.
- Capture final photos, serial numbers, port labels, screenshots, timestamps, and test results required by the ticket.
- Update the asset or cabling record when the change altered inventory or topology.
- Record deviations, delays, aborts, rollback actions, or unexpected observations truthfully.
- Obtain the required technical or customer confirmation before closing the work order.
Equinix demonstrates submission of a trouble ticket, one of the mechanisms used to create a traceable request and route on-site work.
A Technician Remote-Hands Checklist
- Read the full ticket, not only the short description.
- Confirm authorization, maintenance window, contact method, and escalation path.
- Verify site, room, cage, rack, U position, asset identity, serial number, and target component or port.
- Review the current approved SOP or MOP and verify revision number when applicable.
- Confirm prerequisites, tools, spares, ESD controls, PPE, and any site safety requirements.
- Capture the relevant pre-change state.
- Perform a verbal or written read-back of critical identifiers when coordinating remotely.
- Execute one approved action at a time.
- Check the expected result after each critical step.
- Stop at any mismatch, unexpected alarm, degraded redundancy, unclear instruction, or failed hold point.
- Use only the approved rollback plan if rollback is required.
- Verify the final physical and logical state.
- Restore doors, covers, blanks, cable management, labels, and housekeeping.
- Capture final evidence and update inventory or topology records if required.
- Close the ticket only after the responsible team confirms the intended service result.
Hands-On Exercise
Create a mock remote-hands ticket for replacing one failed redundant server PSU. The exercise should identify the server, rack and U position, failed PSU, replacement part number, surviving power path, pre-change evidence, required authorization, expected indicators, hold point before removal, rollback or abort condition, post-change verification, and closeout evidence. Do not write a universal live PSU replacement sequence; use a specific vendor service manual if the exercise is performed on real hardware.
Then run a tabletop exercise with two people. One person is the remote engineer and one person is the on-site technician. The remote engineer may issue only one action at a time. The technician must read back identifiers before any action that changes hardware state. Insert one deliberate mismatch into the ticket, such as the wrong rack or PSU number, and verify that the technician stops instead of improvising.
Knowledge Check
- What is the primary role of remote hands in a data center?
- Why is the work ticket an authorization boundary?
- What is the practical difference between an SOP, MOP, and EOP?
- What is a hold point?
- Name four identifiers that should be verified before touching a device.
- Why should pre-change evidence be captured?
- What should happen if the physical rack state does not match the approved procedure?
- Why is rollback different from open-ended troubleshooting?
- Who should verify the application-level result when the on-site technician cannot see it?
- What evidence should be recorded before a remote-hands ticket is closed?
Knowledge Check Answers
- To provide controlled physical interaction with data center equipment for a remote customer, engineer, or operations team.
- Because it defines exactly which work is approved; nearby or related actions are not automatically authorized.
- An SOP governs routine repeatable operations, a MOP governs a specific planned change, and an EOP governs abnormal or emergency response.
- A required pause where a condition, result, or approval must be confirmed before proceeding.
- Examples include site, room or cage, rack, U position, hostname, asset tag, serial number, component ID, port, and cable label.
- It establishes the known starting state and makes later verification or incident reconstruction possible.
- Stop, preserve the current state, and escalate the mismatch instead of improvising.
- Rollback follows an approved path back to a prior known-good state; troubleshooting can introduce unapproved new actions and a larger failure domain.
- The remote engineer, service owner, or application owner responsible for that layer should confirm it.
- Final physical state, health checks, alarms, serial numbers, cabling or port information, timestamps, photos or logs, any deviations, and confirmation of the intended service result.
References and Prior Lessons
- Equinix — About Smart Hands
- Equinix — Smart Hands Videos
- NIST SP 800-128 — Guide for Security-Focused Configuration Management of Information Systems
- Uptime Institute — The Making of a Good Method of Procedure
- Schneider Electric — Data Center Operations Change Management
- OSDCTC.010: Server FRU Replacement and Change Verification
- OSDCTC.008: Server Network Configuration and Validation
- OSDCEC.007: Data Center Reliability Engineering
BitcoinVersus.Tech Editor’s Note:
We volunteer daily to ensure the credibility of the information on this platform is Verifiably True. If you would like to support to help further secure the integrity of our research initiatives, please donate using the QR code provided

For best QR-code scanning results, please scan this donation code from a desktop or larger screen. Mobile screens may prevent camera recognition.
BitcoinVersus.Tech provides technical education and analysis for informational purposes only.


Leave a Reply